Introduction
Every day, countless consumers bank online and stream favorite media programs without pause. However, bad code updates, broken server hardware, and unstable network routes threaten that smooth experience. Site Reliability Engineering steps in to safeguard modern software systems. Technical specialists write smart software routines to keep computers running fast and steady. They merge modern software engineering practices with daily IT operations tasks. As digital platforms expand, companies require strong safeguards to keep services active. This easy walkthrough shows how engineers maintain high platform dependability. Beginners can gain these vital skills through SRESchool.com, an educational platform dedicated to reliability engineering excellence.
What Is SRESchool.com?
Modern engineers use software scripts to steer large computing systems without unexpected interruptions. Think of clean drinking water flowing instantly from a home faucet whenever you turn it. That quiet, dependable performance shows what true service reliability looks like in action. SRE helps technical departments keep customer platforms steady around the clock. Engineers measure system health with numbers and watch visual dashboards for sudden issues. Then, they write automated code so servers resolve common glitches on their own. Next, they analyze past software errors to make underlying systems even sturdier. This deliberate approach keeps online shops and games operational every minute.
Why Does SRESchool.com Matter?
Modern companies rely heavily on distributed networks, cloud instances, SQL databases, and phone apps. A single syntax error can block millions of customers from submitting their purchases. SRE practices allow engineers to catch small system hiccups before they trigger wide-scale outages. Teams track traffic trends closely and fix emerging bugs before end users encounter errors. Furthermore, product leads must make system resilience a top priority in their daily routines. Dependable architectures protect critical business revenues and win long-term customer trust. Thoughtful engineering ensures that critical applications run reliably during intense holiday sales spikes.
What Does an SRESchool.com Team Do?
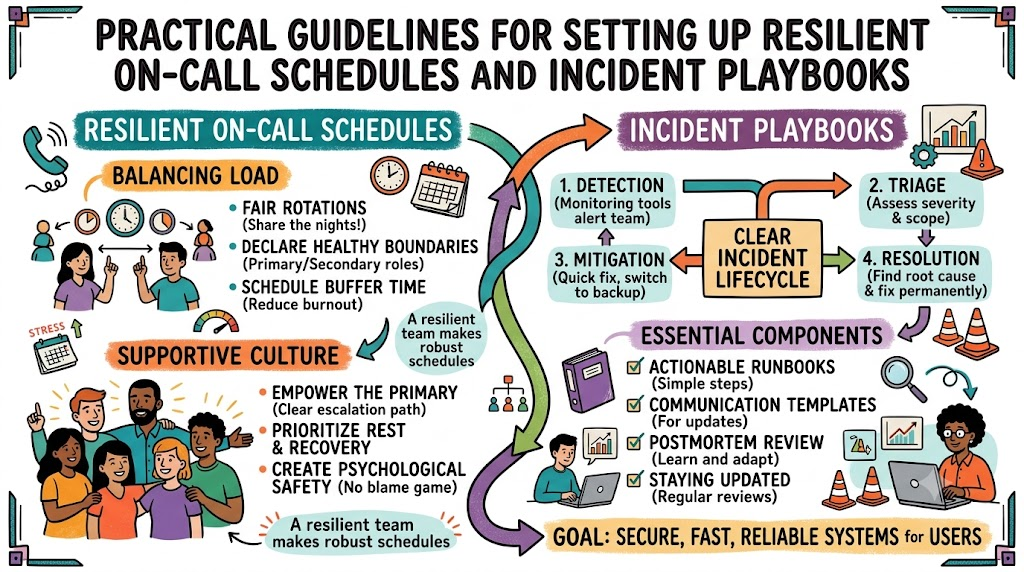
An SRE team tracks server health continuously to spot problems right away. They create high-priority alarm rules that ring engineer phones during serious system failures. Once an alarm rings, they launch incident response efforts to restore broken network connections quickly. They also build automation scripts so operating systems clean up cached files independently. Next, they calculate future resource demands so companies order extra computing capacity before customer traffic swells. They inspect upcoming code changes to confirm that every new update is safe. Finally, they write blameless postmortems that explain past disruptions and show how to prevent future downtime.
Key SRE Terms Made Easy
Reliability engineers use specific performance measurements to track system health across modern platforms. A Service Level Indicator measures exact service performance, such as page load speed. A Service Level Objective sets the target performance benchmark that the development crew plans to maintain. An Error Budget marks the exact slice of downtime a team can safely risk. Toil includes manual, repetitive chores that an engineer can replace with software automation. Observability allows engineers to examine system interiors through logs, traces, and metrics. On-call duty assigns team members to handle emergency outages during designated shifts.
| SRE Term | Simple Meaning | Example |
| SLI | A direct metric showing service speed or system health. | Calculating API response times under one second. |
| SLO | A target performance goal that engineers commit to achieving. | Reaching 99.5 percent successful web requests monthly. |
| Error Budget | The permitted amount of minor downtime or errors. | Allowing twenty minutes of total monthly downtime. |
| Toil | Repetitive administrative tasks that scripts can complete easily. | Manually clearing temporary server log files every morning. |
| Observability | An inside view of system performance via data clues. | Reading telemetry traces to discover database lag. |
| Incident | An unexpected operational disruption that hurts user access. | A database outage during a mobile checkout process. |
What Is SRE Training?
Practical SRE Training teaches students the exact skills required to maintain large cloud systems. Learners study basic reliability principles, track performance metrics, and build automated alerts inside dedicated test environments. They configure visual telemetry screens to assess CPU load and network speeds. Next, they practice incident response routines by fixing simulated platform outages in safe sandboxes. They master cloud resilience strategies, capacity planning rules, and smart techniques to cut down operational toil. Hands-on practice matters because textbook reading alone never prepares engineers for live production crashes. Learners can explore these lessons through SRESchool.com.
What Is SRE Certification?
A recognized SRE Certification proves that a candidate understands how to maintain stable cloud systems. A Certified Site Reliability Engineer demonstrates strong competence in system monitoring, error budget management, and rapid incident recovery. Structured educational courses help candidates absorb essential operational concepts in an organized sequence. However, a paper credential never replaces true hands-on debugging experience on production cloud servers. Students must write working automation code, manage cloud networks, and solve complex server challenges. Combining verified coursework with real project portfolios helps engineers build genuine professional credibility.
What Is a Site Reliability Engineering Course?
A good Site Reliability Engineering Course guides learners through clear, practical milestones. Students start by learning basic Linux commands, networking rules, and cloud infrastructure concepts. Next, they study system monitoring by collecting real performance data using modern observability tools. Then, they establish measurable service targets and set operational error budgets. After that, they learn emergency triage, blameless post-incident reviews, automation programming, and scalable cloud methods. Finally, they apply these modern skills inside realistic test environments that replicate real enterprise platforms. This structured pathway turns novice developers into confident reliability specialists.
SRE Tools Made Simple
Engineers use specialized SRE Tools to inspect, measure, and protect live software systems. Monitoring software collects raw operational numbers, while dashboard platforms turn those numbers into easy charts. Logging frameworks save event records so engineers can investigate past system failures easily. Tracing tools track a single user click as it travels across dozens of microservices. Alerting systems notify engineers only when an urgent infrastructure failure requires human attention. Common platforms include Prometheus for tracking metrics, Grafana for visual dashboards, and OpenTelemetry for traces. These tools give engineers full visibility into complex cloud deployments.
| Learning Area | What Learners Can Practice |
| System Metrics | Collecting server resource trends using Prometheus collectors. |
| Visual Boards | Building custom dashboards to display traffic patterns in Grafana. |
| Event Traces | Following transaction routes across services with OpenTelemetry. |
| Alert Rules | Setting up phone alerts for rising error rates. |
| Task Automation | Writing Python scripts to restart frozen web servers. |
Real-Life Scenarios
- An online shopping portal experiences a massive surge in holiday traffic, and auto-scaling scripts spin up extra servers before transactions freeze.
- A payment system begins dropping transactions silently, but an observability check spots the failure and alerts the on-call engineer within moments.
- A system admin spends two hours manually clearing cache files every morning, so the team writes an automation script to banish the toil permanently.
- A primary database fills its disk storage during peak hours, driving the team to add drive capacity and hold a blameless postmortem to improve capacity planning.
What Is SRE Consulting?
Organizations hire SRE Consulting specialists to audit their production infrastructure and improve team practices. These advisors inspect existing systems to uncover hidden performance bottlenecks and operational risks. They help internal developers define clear service targets and choose optimal monitoring tools. Next, they create structured incident response plans to reduce downtime during unexpected platform failures. Consultants also guide engineering departments in writing automation code that eliminates tedious daily toil. Finally, they deliver an improvement plan that steers the business toward lasting operational stability.
What Is SRE as a Service?
Early-stage companies without dedicated operations staff can turn to SRE as a Service for expert support. Outside engineers monitor cloud systems around the clock to prevent unplanned service interruptions. They handle active system alerts, run routine platform health checks, and patch security vulnerabilities promptly. In addition, they develop automation scripts so common maintenance tasks execute without human labor. Companies must identify their exact operational needs before signing up for managed services. Setting clear expectations ensures that external reliability specialists keep cloud applications fast, dependable, and secure.
What Is Corporate SRE Training?
Corporate SRE Training unites engineering departments around shared reliability goals and proven coding standards. Developers and operations engineers learn to speak the same technical language when discussing uptime, incidents, and platform health. The course teaches consistent monitoring methods, blameless postmortems, and practical automation patterns for company infrastructure. Instructors customize training modules to match the firm’s specific cloud platforms and technical goals. Collaborative team labs allow coworkers to practice fixing simulated outages together in a safe environment. This shared learning builds resilient teams that tackle production challenges with confidence.
Common Mistakes to Avoid When Choosing Delhi Events
- Booking event tickets without reviewing the full agenda leaves you trapped in unhelpful sessions.
- Overlooking the venue location creates long commuting delays through heavy city traffic bottlenecks.
- Skipping background checks on featured speakers often results in basic talks that lack practical value.
- Forgetting to verify workshop prerequisites leaves you without necessary software installed on your laptop.
- Ignoring ticket refund policies causes financial losses if your schedule changes suddenly.
- Skipping organized networking sessions prevents you from meeting local industry contacts.
- Failing to verify on-site Wi-Fi connectivity makes following live technical demonstrations nearly impossible.
- Choosing introductory sessions when you need advanced engineering topics wastes valuable study time.
How SRESchool.com Can Help
SRESchool.com offers comprehensive training courses and professional consulting services focused entirely on system reliability. The platform delivers a structured Site Reliability Engineering Course alongside hands-on SRE Training tracks. Ambitious learners prepare for verified SRE Certification using cloud sandboxes and realistic engineering challenges. Visitors can also explore an introductory SRE Tutorial or learn standard SRE Tools for production monitoring. For enterprises, the team designs custom Corporate SRE Training to align growing technical teams. Furthermore, businesses utilize experienced SRE Consulting and adaptable SRE as a Service packages to protect their core cloud infrastructure.
Frequently Asked Questions
1. Can a complete beginner learn site reliability easily?
Starting engineers can master basic reliability concepts through steady study and hands-on practice. Begin by exploring basic Linux commands, simple computer networking, and entry-level automation scripting. After mastering those core skills, you can advance toward performance metrics and incident triage routines. Regular practice in cloud test environments turns theoretical concepts into intuitive, practical abilities over time.
2. How much coding knowledge does an engineer need?
Engineers need enough coding ability to write automation scripts and inspect software error logs. Most teams rely on languages like Python or Go to query server health endpoints. You will not spend your days building giant consumer mobile applications from scratch. Crafting simple, robust automation code remains the primary development goal for everyday reliability work.
3. What makes this role different from classic operations?
Traditional operations teams performed manual server updates and managed hardware changes using printed checklists. Site reliability engineering uses software code to configure cloud infrastructure and resolve system bugs automatically. Engineers balance their time between managing operational tasks and authoring new software features. This balanced approach eliminates repetitive toil and keeps modern cloud environments running smoothly.
4. Why are error budgets important for product teams?
An error budget sets a safe, agreed-upon limit for temporary application downtime. It balances consumer desire for rapid feature releases against the ongoing need for platform stability. When the budget has plenty of room, developers can push software updates quickly. If an outage drains the budget, the team pauses new releases to fix underlying bugs.
5. What does the term operational toil mean?
Toil describes repetitive, manual operational tasks that do not create lasting value for a system. Examples include rebooting servers by hand, running routine maintenance scripts, or approving standard user permissions manually. Reliability engineers build software automations to replace these tedious manual tasks permanently. Automating basic maintenance frees engineers to design sturdier, more scalable system architectures.
6. How does real-time monitoring protect business profits?
Telemetry agents check server resources and track user requests continuously to catch unexpected software errors early. When error rates rise, the monitoring system notifies on-call staff before shoppers encounter broken checkout pages. Catching problems early prevents wide-scale platform downtime that damages sales and alienates customers. Consistent service uptime protects company revenue and preserves brand reputation across competitive markets.
7. What happens during a standard incident response?
Loud alarms prompt the on-call engineer to log into monitoring dashboards and find the root problem. Responders reroute network traffic or roll back bad code deployments to restore normal service. Afterward, the engineering department holds a blameless postmortem to examine the exact causes of the failure. Team members then build automated safeguards to prevent that specific glitch from happening again.
8. What is the true value of professional certification?
Certifications demonstrate that an engineer understands core reliability concepts, monitoring tools, key metrics, and recovery processes. These credentials help your resume stand out when applying for competitive cloud engineering jobs. However, candidates must also show practical project work and live troubleshooting ability to employers. Pairing verified credentials with authentic hands-on experience generates the best technical career opportunities.
9. Why should an enterprise consider professional consulting?
External consultants examine complex enterprise setups with fresh objectivity to spot dangerous operational oversights. They help internal developers define clear service targets and select optimal monitoring software. Consultants also refine emergency response workflows so internal teams recover quickly from platform outages. Their expert direction saves organizations time and prevents costly operational mistakes during major cloud migrations.
10. How does outsourced reliability support actually work?
External providers monitor cloud systems around the clock to catch emerging platform issues. Their technicians execute scheduled maintenance, install security patches, and support in-house developers during severe outages. This setup helps growing enterprises that cannot yet afford a full internal operations department. It provides enterprise-grade uptime while keeping overall payroll expenses manageable for the company.
11. Which primary tools should a new learner master?
New learners should start with Prometheus for gathering metrics and Grafana for building visual dashboards. Next, explore OpenTelemetry to understand how data requests travel through complex microservice architectures. You should also master container fundamentals using Docker along with basic cloud networking concepts. Learning these foundational tools gives you the practical skills needed for everyday engineering work.
12. Why do engineering teams run blameless postmortems?
Blameless postmortems focus on repairing flawed operational processes rather than punishing individual employees. People make honest mistakes, especially when resolving emergencies under intense workplace pressure. By studying technical failures objectively, teams discover fragile tools and install stronger safeguards. This transparent work culture encourages honest problem reporting and produces resilient digital services.
Conclusion
Through smart code, continuous monitoring, and automated repairs, modern reliability practices keep web platforms running smoothly. They protect essential services from crashing during traffic spikes, helping businesses save money and retain happy users. Anyone can master these valuable skills through organized lessons, hands-on cloud labs, and real-world observability tools. Furthermore, growing companies can use specialized consulting and managed services to audit systems and boost team performance. SRESchool.com equips learners and enterprises with the courses, certifications, and technical guidance needed to build dependable digital systems.
